
Overview
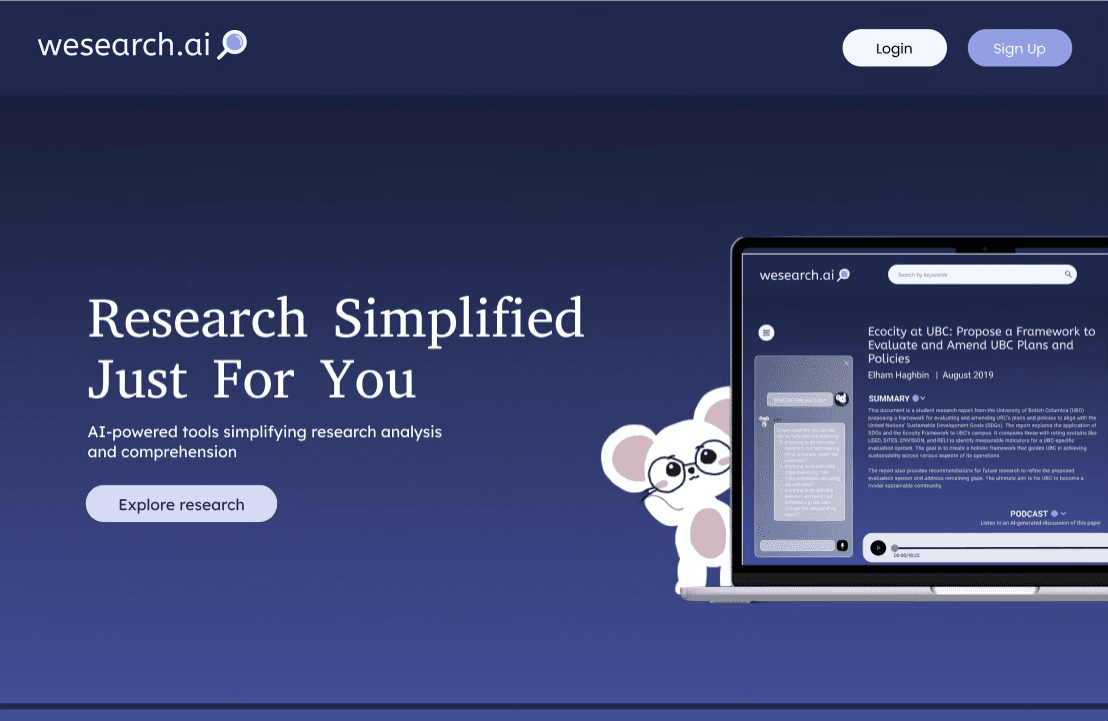
Research shouldn’t require a research background. Academic papers are dense, jargon-heavy, and honestly just slow to get through, even when all you need is one answer buried somewhere in there. WeSearch is a proof-of-concept voice chat interface that lets you just ask the paper your question and get a real answer back, instead of reading the whole thing cold.
Roles
UX Researcher, Designer
Timeline
4 months
Team
Research Accessibility Team
What I owned:
Writing the survey questions, analysing the results, sketching the first user flow, designing the usability test protocol, running all three sessions, and the recommendations that came out of them.
1
The Question.
Academic papers are written for insiders. If you don't have a research background and need one answer from a paper, you face dense, jargon-heavy text that takes a long time to get through.
Research question: What gets in the way when someone without a research background needs one specific answer from a paper?
2
Discovery Survey.
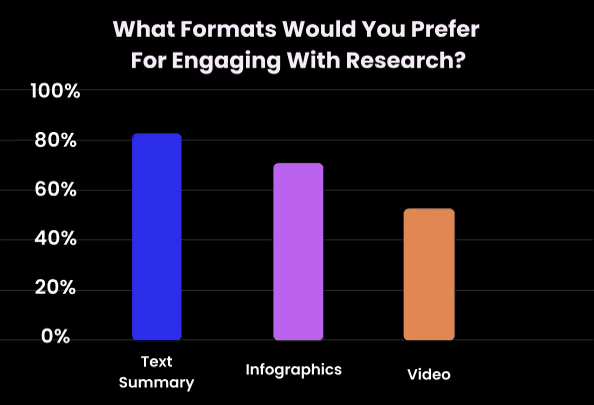
Before anyone opened Figma, we ran a discovery survey. I wrote the questions, covering which tools people use, where they struggle and which techniques help. We reached 98 general-public respondents. I then turned the raw responses into metrics the team could act on.
What we found: three recurring problems
Cognitive overload: difficult to conceptualize dense research and data and identify key takeaways from long papers [80.6%]
Access: difficulty finding relevant and reliable research papers. [59.2%]
• Language: difficult to understand complex terminology or jargon. [80.6%]
From there, we build personas and user stories on miro.
Decision: A conversation, not a search bar. This is where AI became the centre of our project, as asking a question felt more natural and less intimidating than searching a paper. This was a team judgement call that the survey data supported, as well as positive responses during our Sprint Reviews with mentors and peers.
3
Usability Testing.
I designed the test protocol and ran all three sessions. Participants thought aloud while completing tasks in the Figma prototype.
Task: Explore the website with the goal of browsing articles to see an infographic of a complicated science paper, while thinking aloud.
Participants: I recruited students I knew from other programs, who were in research heavy courses.
What I found
Some menu items and pages were unecessary. For example, we had a home page and an explore page, and in this context, there was confusion around what the difference was.
People didn't see that "download" and "read full text" were clickable. [2 out of 3 participants]
Decision: add icons to both actions. I recommended it, and the team shipped it in the prototype.

4
The Outcome.
WeSearch didn't launch. It was a proof of concept for MDIA 470, and university AI policy forced us to change direction instead of pursue the project with UBC stakeholders.
What exists: a working Figma prototype a public GitHub repo and the Miro board.
What the evidence supports, honestly: three informal sessions are a signal, not proof. In that sample, asking the paper a question was easier than reading it cold.
If this went further, I'd measure:
Time to answer: how long it takes to find a specific answer using chat compared with reading the paper.
Task success: whether people complete the same tasks with each approach.
•. Answer accuracy: whether the AI's answers are faithful to the paper. A confident wrong answer is worse than a slow right one.

5
Final Designs


5
The Reflection.
This was the first time I designed inside an actual cross-functional structure, with real constraints I didn’t get to just decide away. I learned so much about how to ask the right questions, the ones that uncover a user's instincts instead of just how it makes them feel. I also learned that to design for a client means being adaptive. During our Sprint Reviews, we would consistently receive feedback that would mean we needed to slightly adjust or reorganize our approach.
What I'd do differently: I would run more sessions, and perform A/B testing to evaluate responses to different forms of AI generated summaries to see which one resonated more. In a university setting you are limited by time, experience and resources, therefore I look forward to performing user research in higher stakes situations.

LS
© Alexandra Smart 2026